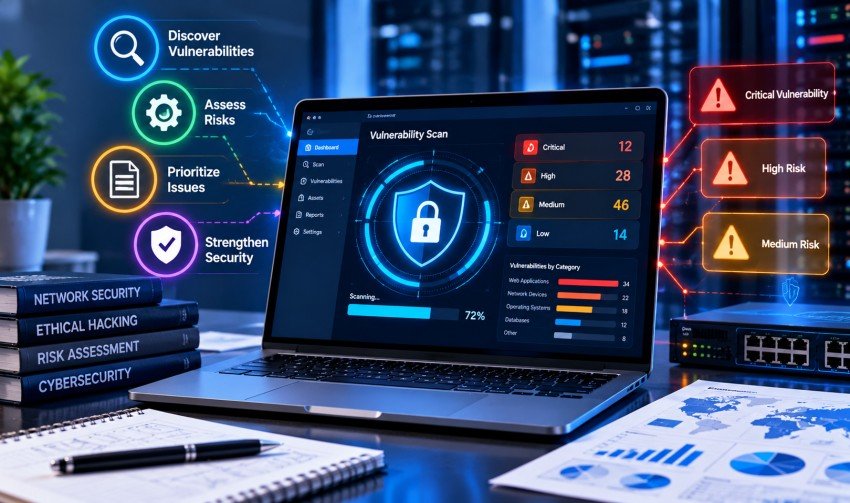

Security teams evaluating vulnerability assessment tools often start by comparing feature lists, only to discover months into deployment that the tool checked every box on paper but still left significant gaps in practice. A scanner might identify thousands of findings and still fail an organization if those findings arrive without context, if the tool misses entire categories of infrastructure, or if remediation never actually happens because the workflow around the tool doesn’t fit how the security team operates. Building a genuinely useful comparison requires looking past marketing claims and evaluating tools against the specific dimensions that determine whether a scanner produces real security improvement or just an ever-growing report nobody acts on.
Assessing Coverage Across the Full Environment
Coverage determines whether a vulnerability assessment tool can even see the parts of an environment that matter most, and gaps here undermine every other strength a tool might have. A scanner excellent at identifying application-layer flaws but blind to cloud misconfigurations leaves an organization with a false sense of security, since the areas it doesn’t cover don’t show up as clean, they simply don’t appear in results at all.
Evaluating coverage means mapping a tool’s stated capabilities against the actual composition of an organization’s infrastructure: web applications, cloud resources across whichever providers are in use, container images, and any on-premises systems that remain in the mix. Organizations running hybrid environments need particular attention here, since some tools built primarily for cloud-native infrastructure handle on-premises systems as an afterthought, with weaker detection and less frequent updates for those environments compared to their cloud-focused capabilities.
Evaluating Accuracy and False Positive Rates
A vulnerability assessment tool that generates excessive false positives creates a different but equally damaging problem than one with coverage gaps. Security teams that spend hours investigating findings that turn out to be non-issues quickly develop alert fatigue, and once that fatigue sets in, genuine critical findings risk getting the same skeptical, delayed treatment as the noise surrounding them. This dynamic explains why raw finding count means relatively little without understanding how many of those findings represent real, actionable risk.
Testing accuracy during evaluation typically involves running a tool against a known environment where the actual vulnerabilities are already understood, then comparing the tool’s output against that baseline. A tool that surfaces the genuine issues while generating a manageable number of false positives proves more valuable in daily use than one that technically catches more total vulnerabilities but buries them under noise. Requesting reference customers with similar infrastructure, and asking directly about their experience with false positive rates, often reveals more than a vendor’s own accuracy claims.
Comparing Prioritization Capabilities
Raw vulnerability counts tell security teams little about where to focus limited remediation resources, which makes prioritization one of the more consequential differentiators between vulnerability assessment tools. A basic scanner might rank findings purely by a generic severity score pulled from a vulnerability database, while a more context-aware platform may also consider exploitability, whether the affected system is internet-facing, and whether the vulnerable component is actually exercised.
A useful evaluation framework should examine several prioritization factors together:
- Whether the tool considers actual exploitability, not just a generic severity rating from a public database.
- Whether findings are weighted by the affected system’s exposure, distinguishing internet-facing assets from internal ones.
- Whether the tool accounts for compensating controls already in place, such as network segmentation limiting a vulnerability’s practical impact.
- Whether prioritization output translates into a clear, ranked action list rather than a flat report requiring manual triage.
Tools that get this right save security teams substantial time by surfacing the handful of findings that genuinely warrant urgent attention, rather than leaving that triage work entirely to already-stretched staff.
Checking Integration Depth With Existing Systems
A vulnerability assessment tool that operates in isolation from the rest of an organization’s security and development tooling creates extra manual work at every step, from pulling findings into a ticketing system to correlating results with other security data. Strong integration capability means findings flow naturally into the tools teams already use daily, rather than requiring someone to manually export reports and re-enter data elsewhere.
Evaluating this dimension means checking specifically for native integrations with the ticketing systems, CI/CD pipelines, and security information platforms an organization already relies on, rather than accepting a general claim of broad compatibility. A tool that integrates deeply with a handful of commonly used platforms, allowing findings to automatically generate tickets assigned to the right team, often delivers more practical value than one boasting a longer list of shallow, loosely supported integrations. Testing this during a trial period, by actually connecting the tool to existing systems rather than reviewing integration documentation alone, tends to reveal gaps that marketing materials gloss over.
Weighing Remediation Workflow Support
Identifying vulnerabilities accomplishes little if the path from finding to fix remains unclear or overly manual. Remediation workflow support covers how well a tool helps teams actually resolve what it finds, including clear guidance on how to fix a given vulnerability, tracking of remediation progress over time, and verification that a fix genuinely resolved the underlying issue rather than just suppressing the finding.
Organizations comparing options should look closely at whether a tool provides specific, actionable remediation guidance tailored to the finding, versus a generic description copied from a public vulnerability database. Tracking capability matters just as much: a tool that shows remediation trends over time, flags findings that have remained open past a defined threshold, and confirms resolution through follow-up scanning gives security teams a genuine feedback loop rather than a static snapshot that goes stale the moment it’s generated.
Building a Structured Comparison Process
Bringing these five dimensions together into an actual evaluation requires more than reading vendor documentation side by side. Running a proof of concept against real infrastructure, ideally including edge cases specific to an organization’s environment, reveals gaps that sales demonstrations rarely surface. Involving the staff who will use the tool daily during evaluation, rather than leaving the decision entirely to leadership reviewing a feature comparison spreadsheet, also tends to catch usability issues that affect whether a tool gets used consistently once it’s deployed.
Weighting these five factors according to an organization’s specific priorities matters more than treating them as equally important across every evaluation. A smaller team with limited remediation capacity might weigh prioritization and workflow support more heavily than an organization with dedicated staff who can manually triage a larger volume of raw findings. There’s no universal ranking that fits every organization, which is exactly why a structured framework, applied deliberately rather than skipped in favor of a quick feature comparison, produces a more reliable decision.
Key Takeaways
Comparing vulnerability assessment tools effectively means looking past headline feature counts and evaluating coverage, accuracy, prioritization, integration depth, and remediation workflow support as the factors that actually determine whether a tool improves security outcomes. A tool that excels in one dimension while falling short in others can still leave meaningful gaps, whether that means missed infrastructure, alert fatigue from false positives, or findings that accumulate without ever reaching resolution. Organizations that build their evaluation around this fuller framework, testing tools against real infrastructure and involving the people who’ll use them daily, end up with a selection that holds up well beyond the initial trial period rather than one chosen on the strength of a polished sales pitch alone.